
Key findings
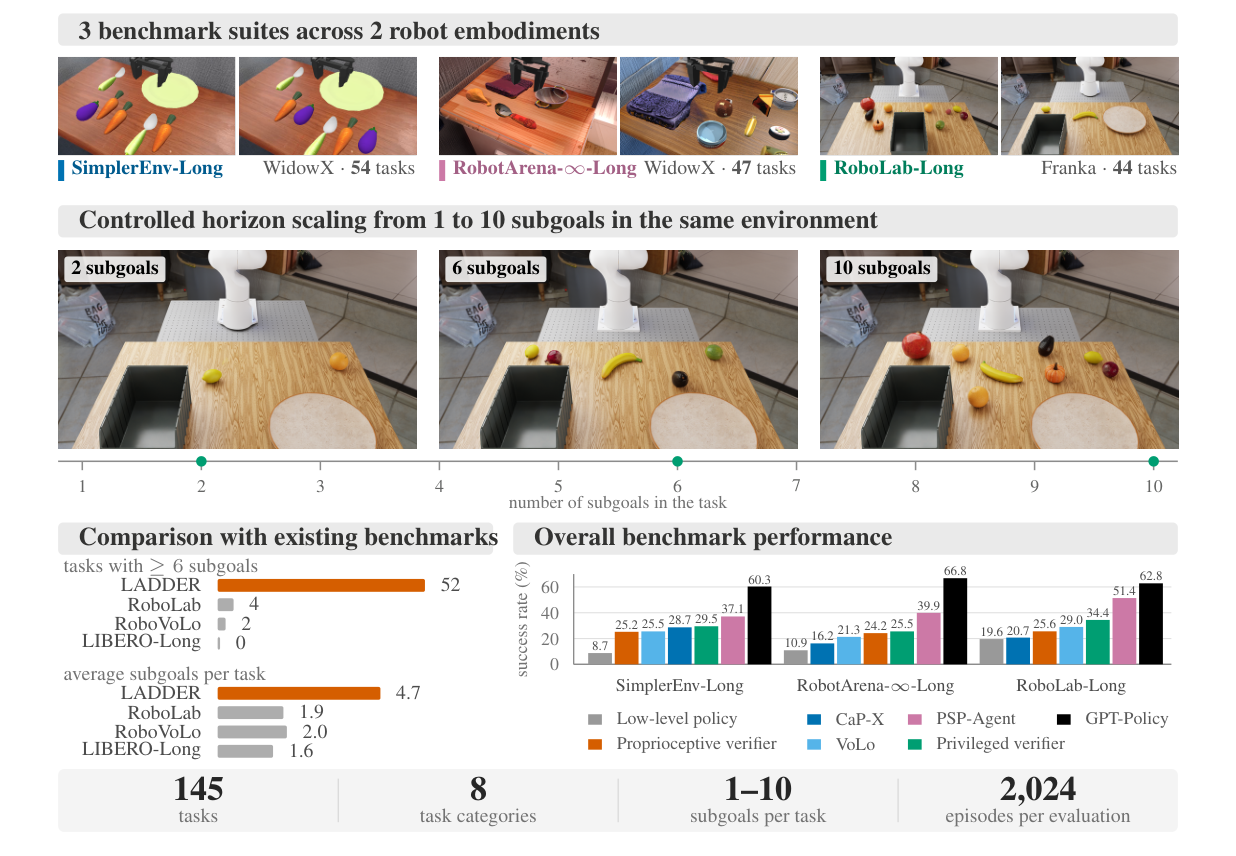
Benchmark
145 tasks in three simulators, each with 1 to 10 subgoals.
RoboLab-Long
44 tasks · Isaac Sim · Franka FR3
low-level policy: π0.5 (DROID)
SimplerEnv-Long
54 tasks · SAPIEN · WidowX 250
low-level policy: Bridge policy
RobotArena-∞-Long
47 tasks · Genesis · WidowX 250
low-level policy: Bridge policy
Eight task categories
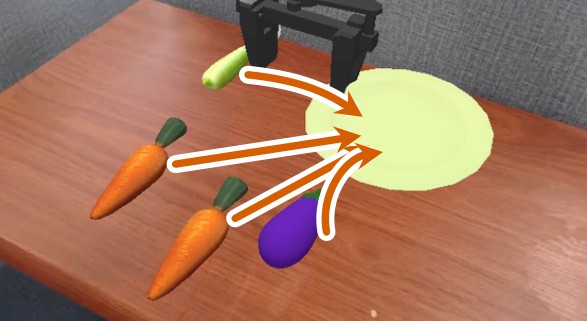
Single destination 44 tasks
Every object goes to the same destination.
“put both carrots, the spoon and the eggplant on the plate”
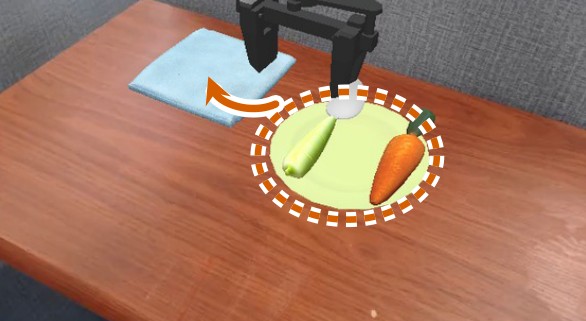
Transfer 8 tasks
Every object starts on one destination and is moved to another.
“move the carrot and the spoon from the plate to the blue towel”
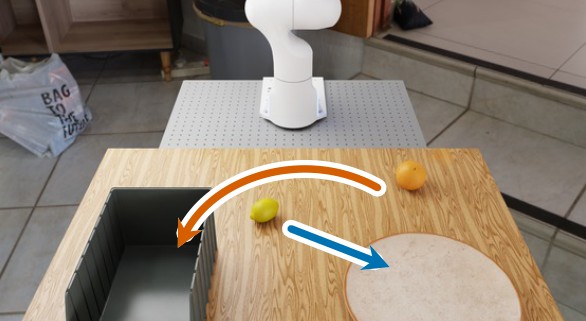
Split destination 25 tasks
Different objects go to different destinations.
“put the lemon on the plate and put the orange in the bin”
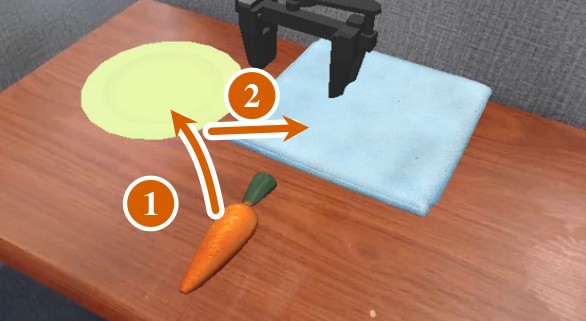
Relay 20 tasks
Objects pass through an intermediate destination.
“first put the carrot on the plate, then put the carrot on the blue towel”
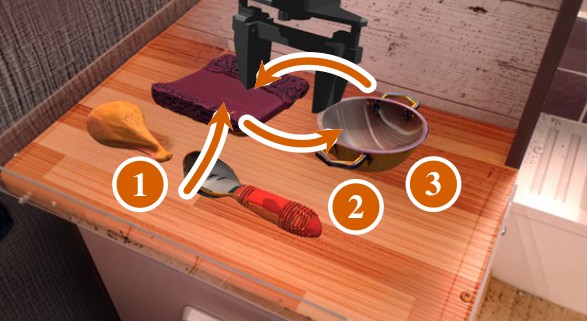
Revisit 13 tasks
Objects return to a destination they have already left.
“first put the spoon on the cloth, then put the spoon in the pot, then put the spoon on the cloth”
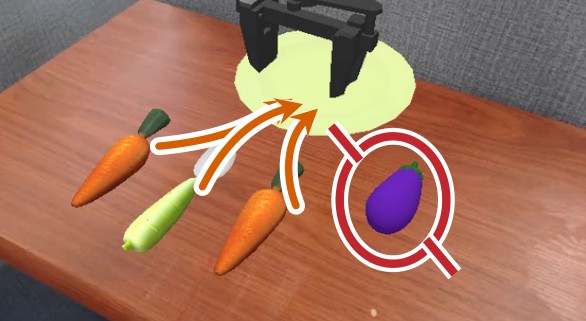
Exclusion 13 tasks
Some objects must be left where they are.
“put everything except the eggplant on the plate”
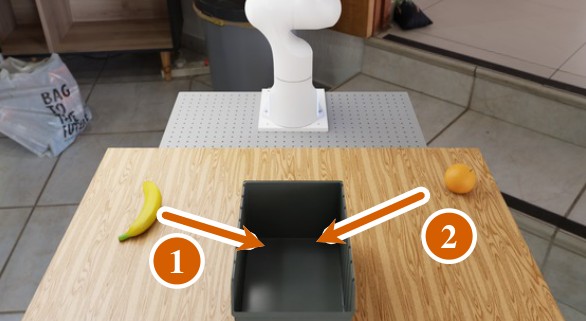
Ordered 14 tasks
The placements must occur in a stated order.
“first put the banana in the bin, then put the orange in the bin”
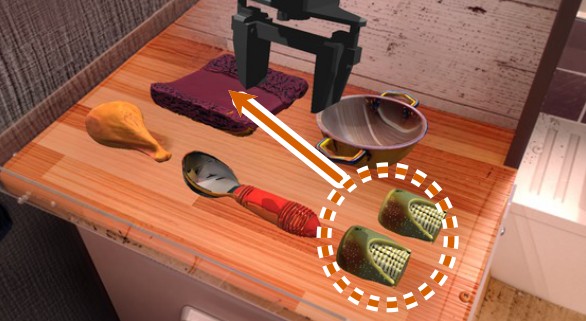
Duplicates 8 tasks
Several identical objects, so the instruction refers to them by count, not by name.
“put both corn cobs on the cloth”
The systems
Same task, ten ways to solve it. Pick one to see how it works.
A robotics model on its own, trained only on robot data, gets the whole instruction and the camera picture, and moves the arm directly. No plan, no checks.
Side by side
How each system plans, when it moves on, how it checks a step and what it does after a failure.
| System | VLM | Execution | Plan | Trigger | Verification | Recovery |
|---|---|---|---|---|---|---|
| End-to-end | ||||||
| Low-level policy | – | Learned policy | None | None | None | None |
| Orchestrated low-level policy | ||||||
| Periodic trigger | – | Learned policy | Text subgoals | Periodic | None | Advance |
| Proprioceptive trigger | – | Learned policy | Text subgoals | Proprioceptive | None | Advance |
| Proprioceptive verifier | Gemini 3.7 Flash | Learned policy | Text subgoals | Proprioceptive | Visual (VLM) | Retry |
| VoLo | Gemini 3.7 Flash | Learned policy | Text subgoals | Periodic | Visual (VLM) | Replan |
| Tool selection | ||||||
| CaP-X | Gemini 3.7 Flash | Motion primitives | Python program | Program completion | Visual (VLM) | Replan |
| TiPToP | Gemini 3.7 Flash | Symbolic TAMP | Goal predicates | None | None | None |
| PSP-Agent | Gemini 3.7 Flash | Motion primitives | Text subgoals | Primitive completion | Geometric state | Retry, replan |
| GPT-Policy | GPT-6 Astra | Motion primitives | Next tool call | Primitive completion | Visual (VLM) | Replan |
| Privileged reference | ||||||
| Privileged verifier | – | Learned policy | Ground-truth subgoals | Privileged | Simulator state | Retry |
Results
A VLM that only looks at the camera gets the robotics model most of the way to perfect step checks. What is left is the robotics model itself.
On 5-subgoal tasks, PSP-Agent's ready-made skills beat even perfect checks on top of a robotics model. Today the learned policy, not the planner, is the bottleneck.
Tasks where some objects must stay put ("everything except the eggplant"): the robotics-only model moves the wrong objects. One step at a time, it gets them right.
| System | RoboLab-Long | SimplerEnv-Long | RobotArena-∞-Long | Mean | Subgoals done |
|---|---|---|---|---|---|
| End-to-end | |||||
| Low-level policy | 19.6±4.5 | 8.7±1.7 | 10.9±3.6 | 13.1±1.8 | 31.8 |
| Orchestrated low-level policy | |||||
| Periodic trigger | 25.6±4.8 | 17.4±2.2 | 15.2±4.0 | 19.4±2.1 | 41.8 |
| Proprioceptive trigger | 28.1±4.9 | 21.5±2.3 | 16.2±4.1 | 21.9±2.1 | 44.5 |
| Proprioceptive verifierGemini 3.7 Flash | 25.6±4.8 | 25.2±2.4 | 24.2±4.6 | 25.0±2.2 | 46.9 |
| VoLoGemini 3.7 Flash | 29.0±4.9 | 25.5±2.4 | 21.3±4.4 | 25.3±2.2 | 47.4 |
| Tool selection | |||||
| CaP-XGemini 3.7 Flash | 20.7±4.5 | 28.7±2.5 | 16.2±4.1 | 21.9±2.1 | 39.3 |
| TiPToPGemini 3.7 Flash | 17.3±4.3 | 6.7±1.5 | 11.2±3.6 | 11.7±1.8 | 14.0 |
| PSP-AgentGemini 3.7 Flash | 51.4±5.2 | 37.1±2.7 | 39.9±5.0 | 42.8±2.6 | 63.3 |
| GPT-PolicyGPT-6 Astra | 62.8±5.2 | 60.3±2.7 | 66.8±4.9 | 63.3±2.5 | 81.8 |
| Privileged reference | |||||
| Privileged verifier | 34.4±5.1 | 29.5±2.5 | 25.5±4.6 | 29.8±2.4 | 49.5 |
| Scored on LADDER-Lite only | |||||
| Gemini 4 Argonvia GPT-Policy, LADDER-Lite | 50.0±17.3 | 77.1±11.9 | 40.6±17.0 | 55.9±9.0 | 74.2 |
| Claude Opus 5.5via GPT-Policy, LADDER-Lite | 59.4±17.0 | 62.5±13.7 | 25.0±15.0 | 49.0±8.8 | 65.6 |
Task success (%) with 95% Wilson intervals. Mean: the three suites weighed equally, as on the leaderboard. Subgoals done: the share of all subgoals completed. Bold: best system, the privileged reference aside. Systems scored on LADDER-Lite only are on its 10 tasks, so their numbers are not on the same tasks as the rows above.
Task success by number of subgoals
Task success (%), the three simulators weighed equally. Subgoal counts are grouped so every point covers many tasks. Hover the chart to read the values. Click a name to show or hide it.
By task category
| System | Single destination | Transfer | Split destination | Relay | Revisit | Exclusion | Ordered | Duplicates |
|---|---|---|---|---|---|---|---|---|
| End-to-end | ||||||||
| Low-level policy | 33.5 | 30.1 | 4.9 | 1.1 | 0.0 | 0.6 | 23.8 | 58.4 |
| Orchestrated low-level policy | ||||||||
| Periodic trigger | 40.8 | 25.7 | 11.7 | 8.7 | 2.8 | 35.9 | 27.1 | 47.2 |
| Proprioceptive trigger | 38.3 | 27.5 | 12.3 | 12.1 | 2.8 | 39.2 | 31.0 | 59.0 |
| Proprioceptive verifier | 42.9 | 26.0 | 17.6 | 17.6 | 6.9 | 34.1 | 39.1 | 51.7 |
| VoLo | 43.9 | 32.5 | 21.8 | 15.1 | 7.3 | 32.5 | 42.8 | 57.3 |
| Tool selection | ||||||||
| CaP-X | 31.7 | 43.9 | 18.7 | 21.3 | 7.3 | 41.8 | 31.5 | 42.7 |
| TiPToP | 21.1 | 31.8 | 17.8 | 0.6 | 0.0 | 18.1 | 14.6 | 31.2 |
| PSP-Agent | 52.4 | 69.0 | 65.4 | 27.8 | 4.2 | 56.5 | 62.0 | 71.9 |
| GPT-Policy | 72.2 | 70.4 | 59.2 | 70.4 | 42.4 | 65.6 | 73.8 | 76.4 |
| Privileged reference | ||||||||
| Privileged verifier | 45.4 | 32.2 | 22.6 | 29.6 | 9.4 | 45.7 | 43.3 | 53.1 |
Task success (%) per task category, the three suites weighed equally.
Cost
Cost per successful episode of GPT-Policy with GPT-6 Astra and of PSP-Agent with Gemini 3.7 Flash. One full run of GPT-Policy on LADDER costs up to $8,134.
The leader pays 36 times more per finished task than the Proprioceptive verifier, for 2.5 times its success. A small VLM that only checks steps is the cheapest way to add reliability.
Subgoals done by the Proprioceptive verifier at half the time limit, and at the end. Failures are not a lack of time: more time would add little.
| System | VLM | VLM calls per episode | Cost per episode | Cost per success | Task success |
|---|---|---|---|---|---|
| GPT-Policy LADDER-Lite | Claude Opus 5.5 | 63.1 | $3.575 | $7.02 | 49.0% |
| GPT-Policy | GPT-6 Astra | 54.2 | $4.019 | $6.49 | 63.3% |
| GPT-Policy LADDER-Lite | Gemini 4 Argon | 38.0 | $0.784 | $1.33 | 55.9% |
| VoLo | Gemini 3.7 Flash | 23.5 | $0.166 | $0.66 | 25.3% |
| PSP-Agent | Gemini 3.7 Flash | 23.3 | $0.133 | $0.33 | 42.8% |
| Proprioceptive verifier | Gemini 3.7 Flash | 10.4 | $0.045 | $0.18 | 25.0% |
| CaP-X | Gemini 3.7 Flash | 5.2 | $0.042 | $0.17 | 21.9% |
| TiPToP | Gemini 3.7 Flash | 1.0 | $0.007 | $0.07 | 11.7% |
API cost at list prices on 25 September 2026, from each provider's token counts. It covers only the hosted VLM, not the GPU time of the low-level policy or the simulators. The usage reports do not say how much input was cached, so GPT-Policy's cost is an upper bound. Calls: mean of the three suites. Rows marked LADDER-Lite are scored on its 10 tasks only. For Gemini 4 Argon the gateway omits the output-token count on most calls; those are estimated from the calls of the same run that report it, about 5% of its cost.
Why subgoals fail
Subgoals lost to an orchestrator decision: Proprioceptive verifier against Periodic trigger, which never checks. Once subgoals are checked, most failures come from the policy.
Subgoals never started in 10-subgoal tasks, the largest cause on long tasks. Systems that retry run out of time on earlier subgoals.
Subgoals for which TiPToP finds no plan. Its planner fails more often as tasks get longer.
(a) Per system, all tasks
(b) Per task length, all systems
Share of subgoals not completed at the end of the episode, by the stage where they were lost, averaged over the three suites. Orchestrator decision: a planner or verifier mistake made the loss final (moved on too early, no plan found). The other stages describe what happened to the object. Hover a bar for its value.
Which VLM plans best
Mean score of Gemini 3.7 Flash, the highest of the ten VLMs. Other models lead single columns. All orchestrators in the results use Gemini 3.7 Flash.
Exact plans from every model except the smallest. Writing the plan is easy. Seeing from a picture whether a step is really done is where models differ: the best tracks every step only 70.8% of the time.
| Model | Plan exactly right | Sees a step done when it is | Sees a step not done when it is not | Tracks every step all correct | Picks the next step valid | Tokens per question |
|---|---|---|---|---|---|---|
| Qwen3-VL-2B | 75.2 ±7.6 | 68.2 ±7.0 | 34.1 ±5.9 | 9.3 ±4.0 | 58.9 ±5.3 | – |
| Qwen3-VL-8B | 91.0 ±5.8 | 69.0 ±6.8 | 79.9 ±5.7 | 47.9 ±5.5 | 72.3 ±4.4 | – |
| Qwen3.5-9B | 86.9 ±6.5 | 44.4 ±6.3 | 96.9 ±2.5 | 11.7 ±3.7 | 63.2 ±4.8 | 5,173 |
| Qwen3.8-27B | 91.0 ±5.8 | 76.2 ±6.3 | 84.8 ±4.3 | 58.2 ±4.8 | 79.3 ±4.1 | 1,904 |
| Gemini 3.1 Pro | 89.7 ±6.0 | 54.8 ±6.6 | 96.0 ±2.9 | 68.7 ±4.3 | 75.2 ±4.5 | 583 |
| Gemini 3.7 Flash | 93.1 ±5.4 | 59.4 ±6.6 | 96.6 ±2.6 | 70.8 ±4.0 | 81.4 ±4.2 | 412 |
| Gemini Robotics-ER 2 | 90.3 ±5.9 | 54.0 ±6.5 | 97.8 ±2.3 | 69.6 ±4.2 | 76.6 ±4.1 | 510 |
| GPT-5.6 Sol | 93.1 ±5.4 | 72.8 ±6.3 | 86.4 ±4.3 | 56.4 ±4.7 | 82.0 ±4.3 | 282 |
| GPT-6 Astra | 91.7 ±5.7 | 71.1 ±6.2 | 86.4 ±4.4 | 53.2 ±5.1 | 85.4 ±4.0 | 203 |
| Claude Opus 5 | 90.3 ±5.9 | 68.6 ±6.6 | 87.9 ±4.1 | 61.0 ±4.7 | 79.8 ±4.4 | 400 |
Each VLM answers the questions an orchestrator asks, from still pictures and without running the robot: 145 scenes and 562 labelled frames. Scores in % with 95% intervals.
Real robots
On both robots: robotics-only model, then Proprioceptive verifier, then PSP-Agent, as in simulation.
Tasks with 2 to 5 subgoals finished on the real WidowX: the robotics-only model, the Proprioceptive verifier, and PSP-Agent. Breaking a task into checked steps helps on hardware too.
| Task category | Subgoals | Low-level policy | Prop. verifier | PSP-Agent |
|---|---|---|---|---|
| Franka | ||||
| Single destination | 5 | 0.0 | 8.3 | 25.0 |
| Exclusion | 2 | 0.0 | 83.3 | 100.0 |
| Ordered | 3 | 16.7 | 83.3 | 100.0 |
| WidowX | ||||
| Single destination | 1 | 66.7 | 75.0 | 100.0 |
| Single destination | 2–3 | 0.0 | 33.3 | 87.5 |
| Split destination | 2–3 | 0.0 | 29.2 | 83.3 |
| Exclusion | 2 | 0.0 | 58.3 | 91.7 |
| Ordered | 2 | 8.3 | 33.3 | 41.7 |
| Duplicates | 2 | 0.0 | 0.0 | 58.3 |
Real-robot videos
Each video is typical for its system on that task: a success if it succeeds in at least half of its attempts.
“Put the corn, the carrot, the eggplant, the blue cup and the banana in the bowl”
“First put the blue cup in the bowl, then put the carrot in the bowl, then put the eggplant in the bowl”
“Put everything except the eggplant in the bowl”
“Put the corn, the carrot, the eggplant, the blue cup and the banana in the bowl”
“First put the blue cup in the bowl, then put the carrot in the bowl, then put the eggplant in the bowl”
“Put everything except the eggplant in the bowl”
“Put the corn, the carrot, the eggplant, the blue cup and the banana in the bowl”
“First put the blue cup in the bowl, then put the carrot in the bowl, then put the eggplant in the bowl”
“Put everything except the eggplant in the bowl”
“put both the eggplant and the cup on the cloth and put the carrot in the pot”
“put everything in the pot”
“put everything except the eggplant in the pot”
“put both the eggplant and the cup on the cloth and put the carrot in the pot”
“put everything in the pot”
“put everything except the eggplant in the pot”
“put both the eggplant and the cup on the cloth and put the carrot in the pot”
“put everything in the pot”
“put everything except the eggplant in the pot”
Videos
The label on each video gives its playback speed.
44 tasks · Isaac Sim · Franka FR3 · low-level policy: π0.5 (DROID)
Highlights: long tasks solved without a single mistake
CaP-X
“first put the orange in the bin, then put the pumpkin in the bin, then put the lychee in the bin, then put the lemon in the bin, then put the lime in the bin, then put the banana in the bin, then put the onion in the bin, then put the avocado in the bin”
GPT-Policy
“first put the lemon on the plate, then put the lemon in the bin, then put the lime on the plate, then put the lime in the bin, then put the banana on the plate, then put the banana in the bin”
GPT-Policy
“put the avocado, the banana and the lemon on the plate and put the orange, the lime and the onion in the bin”
One scene, growing horizon
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
“put the banana in the bin”
“put the banana, the orange, the lemon, the lime, the avocado and the onion in the bin”
“put the banana, both oranges, the lemon, the lime, the avocado, the onion, the lychee, the pumpkin and the pomegranate in the bin”
Task categories
Proprioceptive trigger
“move the orange, the lemon and the lime from the plate to the bin”
Privileged verifier
“put everything except the red block and the blue block in the bin”
54 tasks · SAPIEN · WidowX 250 · low-level policy: Bridge policy
Highlights: long tasks solved without a single mistake
CaP-X
“first put the carrot on the plate, then put the spoon on the plate, then put the eggplant on the plate, then put the carrot on the blue towel, then put the spoon on the blue towel, then put the eggplant on the blue towel, then put the carrot on the plate, then put the spoon on the plate, then put the eggplant on the plate, then put the carrot on the blue towel”
PSP-Agent
“first put the carrot on the plate, then put the spoon on the plate, then put the eggplant on the plate, then put the carrot on the blue towel, then put the spoon on the blue towel, then put the eggplant on the blue towel, then put the carrot on the plate”
VoLo
“first put the carrot on the plate, then put the carrot on the blue towel, then put the spoon on the plate, then put the spoon on the blue towel, then put the eggplant on the plate, then put the eggplant on the blue towel”
One scene, growing horizon
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
“put the carrot on the plate”
“put both carrots, both spoons and the eggplant on the plate”
“put the four carrots, the three spoons and the three eggplants on the plate”
Task categories
Proprioceptive verifier
“put both carrots, both spoons and the eggplant on the plate”
Proprioceptive verifier
“first put the carrot on the plate, then put the carrot on the blue towel, then put the spoon on the plate, then put the spoon on the blue towel, then put the eggplant on the plate”
GPT-Policy
“first put the carrot on the plate, then put the spoon on the plate, then put the eggplant on the plate”
47 tasks · Genesis · WidowX 250 · low-level policy: Bridge policy
Highlights: long tasks solved without a single mistake
GPT-Policy
“put the blue bowl, the sushi toy, the cheese, the banana and the mushroom on the purple cloth”
PSP-Agent
“put the blue bowl, the sushi toy, the banana and the cheese on the purple cloth”
VoLo
“put the blue bowl, the sushi toy, the cheese and the banana on the purple cloth”
One scene, growing horizon
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
“put the blue bowl on the purple cloth”
“put the blue bowl, the sushi toy and the banana on the purple cloth”
“put the blue bowl, the sushi toy, the cheese, the banana, the mushroom and the corn cob on the purple cloth”
Task categories
PSP-Agent
“put the spoon and the corn cob on the cloth and put the chicken drumstick in the pot”
GPT-Policy
“first put the spoon on the cloth, then put the spoon in the pot, then put the spoon on the cloth”
GPT-Policy
“put the three corn cobs on the cloth”
One task, every system
RoboLab-Long, 4 subgoals: “put the avocado and the banana on the plate and put the orange and the lime in the bin”. Episodes are sampled at random, so failures are shown where they occurred.
Low-level policy
Periodic trigger
Proprioceptive trigger
Proprioceptive verifier
VoLo
CaP-X
TiPToP
PSP-Agent
GPT-Policy
Privileged verifier
Relay · 6 subgoals: “first put the lemon on the plate, then put the lemon in the bin, then put the lime on the plate, then put the lime in the bin, then put the banana on the plate, then put the banana in the bin”
Low-level policy failure
Proprioceptive verifier success
Ordered · 4 subgoals: “first put the orange in the bin, then put the lemon in the bin, then put the lime in the bin, then put the banana in the bin”
Low-level policy failure
Proprioceptive verifier success
Add your system
Policies, orchestrators and agents can all be evaluated on LADDER.
- Start from the example for your kind of system and replace the model with yours.
- Run all tasks of the three suites, or the 10 tasks of LADDER-Lite for a quick first result.
- Open a pull request with your episode logs. We recompute every score from the logs.
Integration guide How to submit Request a model
Code and data
BibTeX
@article{ladder2026,
  title   = {{LADDER}: A Long-Horizon Robot Manipulation Benchmark},
  author  = {Petkov, Petko and Albanese, Giuliano and Nikolov, Nikolay and Van Gool, Luc and Tremblay, Jonathan and Paudel, Danda Pani},
  journal = {arXiv preprint arXiv:2610.18053},
  year    = {2026},
  url     = {https://arxiv.org/abs/2610.18053}
}